
aHash/dHash/pHash Compare
aHash/dHash/pHash Compare checks two image hash strings with Hamming distance and tells you whether the fingerprints are exact, close, weak, or likely different.
Use it for perceptual hash comparison, duplicate-image review, QA screenshots, moderation queues, and stored image fingerprints when you already have the hash values.
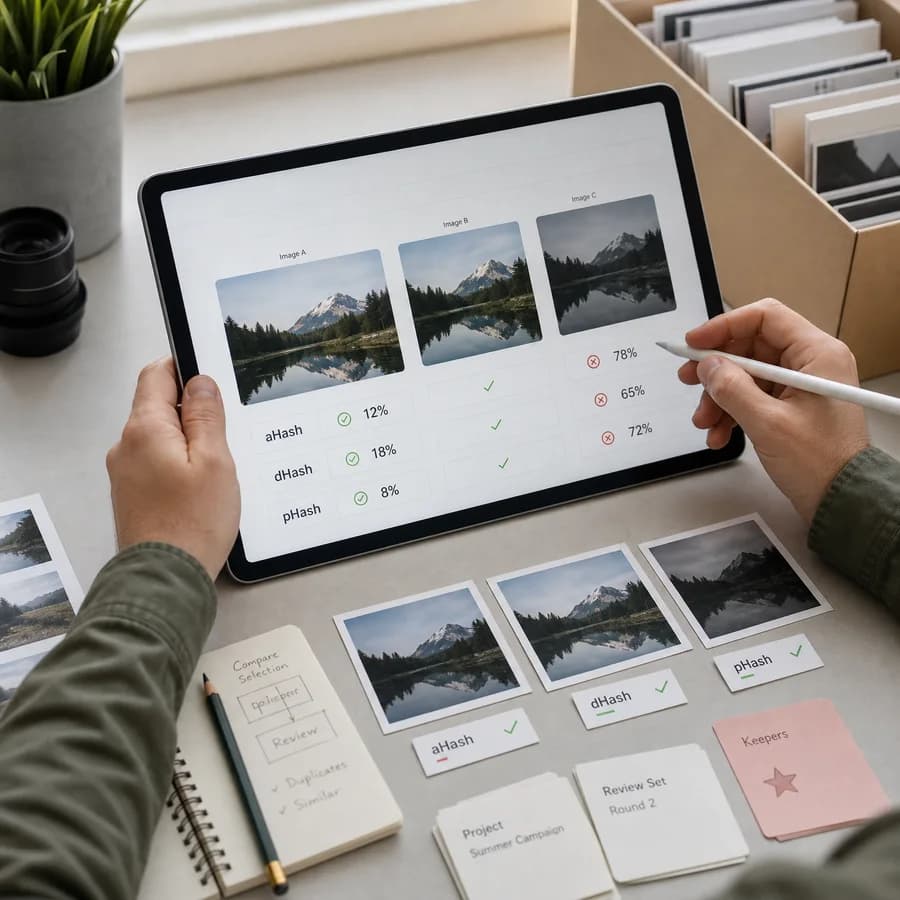
Hash comparison result appears here
Paste two values generated by the same aHash, dHash, or pHash method to calculate Hamming distance and similarity.
Image Hash Comparison Guide
What this hash comparison measures
The tool compares two normalized binary representations of image hashes and counts how many bits differ. That count is the Hamming distance, so a distance of 0 means the hash strings match exactly, while larger values mean the image fingerprints are farther apart.
This is useful when you generated hashes elsewhere, stored them in a database, or copied output from an image hash generator and now need a quick interpretation step.
- Use the same algorithm for both values before comparing.
- Use the same hash length, such as 64-bit against 64-bit.
- Use hex values, binary values, or spaced hash strings; the tool normalizes them before counting bits.
How aHash, dHash, and pHash differ
aHash, dHash, and pHash are perceptual or visual fingerprints, not cryptographic signatures. They are designed so visually similar images can produce similar hashes, which is different from MD5 or SHA-style hashes where a tiny image edit should produce a completely different digest.
aHash is usually the simplest brightness-average method, dHash focuses on neighboring brightness differences, and pHash usually uses a frequency-domain transform such as DCT. Because each algorithm reacts differently to crops, compression, color changes, resizing, and overlays, thresholds must be treated as review guidance rather than proof.
- aHash is fast but can be easier to fool with broad brightness changes.
- dHash often works well for resized or lightly compressed images with similar structure.
- pHash is commonly used for near-duplicate checks because it tends to preserve more visual structure.
Reading the result safely
A low Hamming distance is a signal for visual review. It does not guarantee that two images are the same file, the same original, or the same subject, and a high distance does not always prove two images are unrelated if one image was heavily cropped, rotated, retouched, or overlaid with text.
For 64-bit pHash-style values, a distance near zero is usually a strong match signal. A wider review band can catch edited copies, but it also increases false positives, so production systems should tune thresholds on real examples from the workflow.
- Use exact match when you only trust identical hash values.
- Use close-match ranges for dedupe queues that still include human review.
- Use pixel-by-pixel diff or visual inspection when legal, moderation, or billing decisions depend on the result.
Common mistakes
The most common mistake is mixing algorithms or hash sizes, such as comparing a pHash generated by one library with a dHash generated by another. The second mistake is treating similarity percentage as a universal confidence score when it is only a normalized bit-distance view.
Library implementations can also differ in resize method, grayscale conversion, DCT details, hash length, orientation handling, and output format. If two systems disagree, generate both hashes with the same tool or run a small benchmark on known matching and non-matching images.
- Do not compare hashes from different algorithms as if they are interchangeable.
- Do not compare different bit lengths.
- Do not use perceptual hash distance as a replacement for content review in high-risk workflows.